What should an enterprise learning AI pilot actually prove?
A learning-AI pilot is an experiment intended to inform a decision. It needs an explanation of the task, the existing process and the evidence produced, rather than only a report that participants liked the tool.
Evidence DDecision horizon NowUpdated 09 Oct 2026Proof patterns 1
Editorial context for What should an enterprise learning AI pilot actually prove?
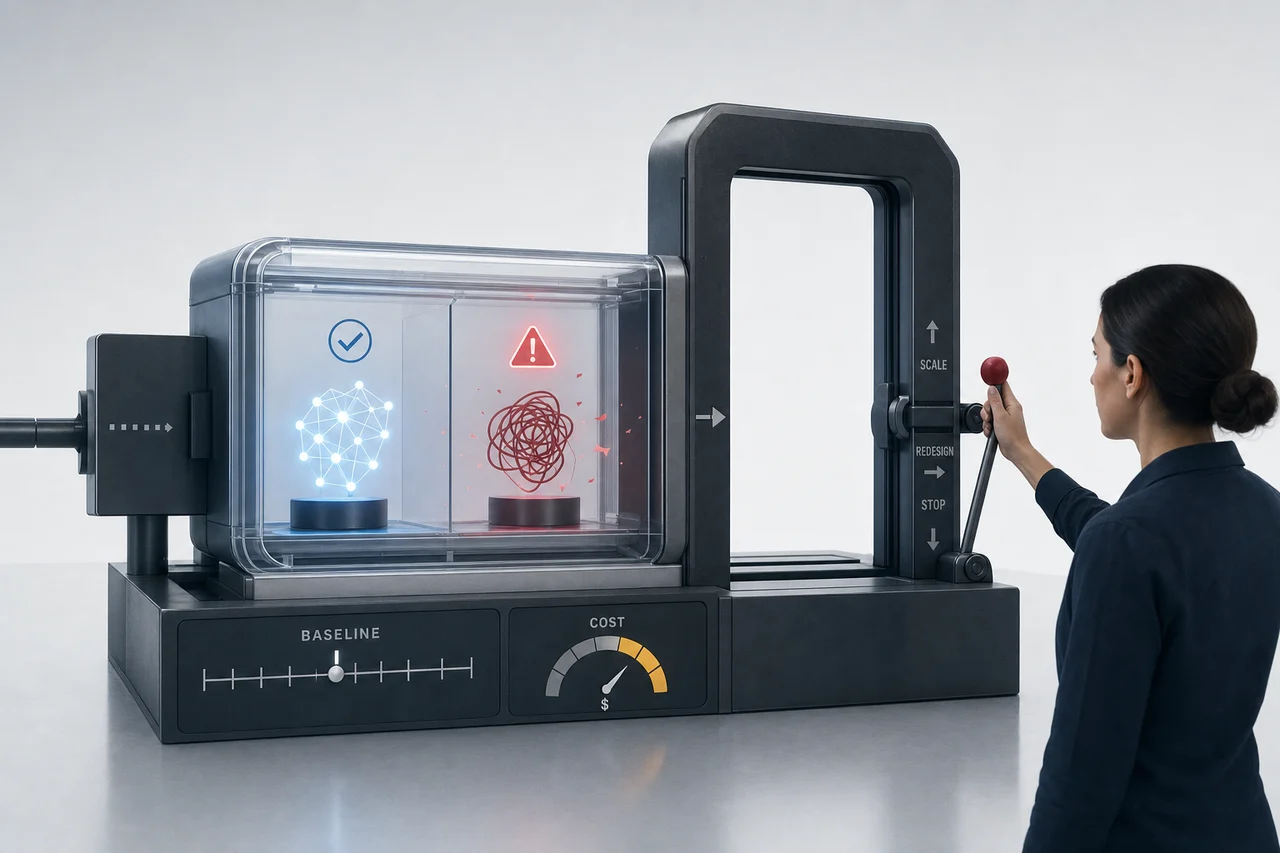
LT Horizon generated editorial illustration · not evidenceImage provenanceLT Horizon Visual Editor v2 · GPT-Image-2 generated editorial illustration; never evidence.
The task determines the evidence
An AI tutor, a course-authoring tool and an administrative agent perform different work. A tutor can be assessed against the explanations and help it supplies; authoring involves the quality and maintenance of a draft; an agent can change a managed resource.
The baseline is the current way of performing that work. Without it, faster generation or positive feedback says little about whether the organisation has improved the complete process. Review, correction and support are part of that process as well as the initial interaction.
A bounded example has a narrower claim
The cited Sana-hosted Gorgias story describes introducing a tutor for a course about a specific product task, grounded in help documentation. It reports learner feedback and task-related outcomes within that setting.
That is useful evidence of a bounded implementation, with stated sources and a defined task. It is not independent proof of long-term retention or an enterprise-wide return on investment. The difference between the observed setting and a proposed larger deployment is part of what the pilot needs to explain.
From activity to a decision
NIST's AI risk-management material provides cross-sector approaches to evaluation and governance. LT Horizon applies those ideas here as an editorial framework: the experiment should produce evidence for expanding, changing or stopping the use case.
That requires attention to unsuccessful interactions as well as successful ones, and to the work people perform around the tool. The guidance below translates this reasoning into pilot design without claiming that one metric or universal threshold fits every learning-AI task.
How to read this briefCheck the sources to see what is documented. Our recommendation explains what that means for your decision. Proof patterns add specific design or implementation examples and explain their limits.
LT Horizon DECISION BRIEF
Answer
Choose a task and record how it works today. Run a limited AI pilot with agreed error limits, a responsible owner and measures of results, review time and cost.
Who should care
Learning technology leaders, AI programme owners, procurement teams, risk leaders and enterprise architects.
Recommended action
PILOT — require every learning-AI experiment to state the decision it will support and the evidence threshold needed to change that decision.
LT Horizon interpretation · Evidence confidence D
What changed
No product event is asserted. This is an LT Horizon framework for converting AI experimentation into decision-quality evidence.
Why it matters
Enterprise learning teams can spend months piloting AI without generating evidence that supports a scale, stop or redesign decision.
Use cases & proof
Where this holds up in practice
These examples show how a specific claim is supported by documentation or an implementation. Read their limits before applying them to your own environment.
Proof pattern · Evidence C
A bounded, grounded AI tutor can be evaluated against real learner tasks
Scenario
An organisation pilots an AI tutor in a deliberately narrow learning domain, grounds it in approved knowledge and evaluates both failure behaviour and whether learners can complete a defined task or learning objective.
Architecture pattern
Approved knowledge sources and permissions → AI tutor → learner interaction → observability, feedback and escalation → measured task or learning outcome; governance and risk controls sit across the full loop.
Observed / documented outcome
Workday positions personalised AI tutors as a capability of Workday Learning, powered by Sana. NIST provides cross-sector AI and generative-AI risk-management guidance for governing, mapping, measuring and managing AI systems. Separately, Gorgias describes a real Sana AI tutor deployment grounded in help documentation for a specific product course and reports positive learner task and feedback signals.
What this proves
A learning AI tutor can be deployed as a bounded, knowledge-grounded interaction and evaluated against both technical failure behaviour and a concrete learner task. This supports piloting with approved sources, explicit success criteria, telemetry and human escalation rather than treating conversational fluency as proof of value.
What it does not prove
It does not prove that Workday Learning, powered by Sana will reproduce the Gorgias outcome, that the Gorgias tutor was independently audited for hallucination or safety, that positive survey feedback establishes durable learning transfer, or that an unrestricted enterprise-wide tutor is appropriate.
Apply with these constraints
Define the approved source corpus, permissions, excluded topics, privacy boundaries, adversarial and outdated-content tests, failure thresholds, human escalation, baseline comparison, task or learning outcome measures and post-pilot decision criteria before expanding scope.
Last checked 18 Sept 2026 · Reviewed before publication.
Implementation implications
Prerequisites
A specific workflow, baseline performance, target population, success measures, failure threshold, human owner, data boundary, review process and post-pilot decision date.
Architecture implications
Pilot architecture should be production-representative enough to reveal identity, data, observability, integration and governance issues without prematurely committing to full-scale design.
Risks
Vanity metrics, selection bias, hidden manual support, weak failure logging, unclear data use, unrepresentative test populations and no explicit decision at the end of the pilot.
Testing implications
Capture successful and failed interactions, compare with baseline, include edge cases, measure reviewer effort, record data and latency constraints and test the escalation route when the AI is uncertain.
Source register
What the evidence establishes
What changed with Workday Learning, powered by Sana? — Workday evidence
Public summary awaiting review. See the original source.
Publication review is recorded in the evidence and correction history. Images illustrate the article; they are not evidence.
History and corrections
Article body revision 1 · added 09 Oct 2026. Explanatory text added to the published evidence snapshot; evidence confidence, availability and source verification dates are unchanged.
Published revisions are retained. Update dates change only after a change to the content or evidence.
Correction: Evidence grade corrected from C to D. This LT Horizon pilot framework has not been validated against implementation outcomes. Wording reviewed for clarity; source verification dates are unchanged. · 30 Sept 2026
Keep a clearer view of learning technology.
Get occasional email updates when LT Horizon publishes new Intelligence and Horizon articles. Free to read, with no account required.
Our practical newsletter format brings one question, one idea and one exercise, alongside selected source-linked articles. Editions follow useful reviewed evidence.